IT teams seek ways to prevent network solutions outages checkerpointorg from causing downtime. The team uses Checkpoint.org to track devices, logs, and alerts. This guide lists clear checks and steps. It helps teams reduce outages, detect issues early, and restore service faster. The writing stays direct and practical so teams can act fast.
Key Takeaways
- Prevent network solutions outages by proactively monitoring devices and network paths using Checkpoint.org’s comprehensive telemetry and alert system.
- Establish clear alerts and dashboards in Checkpoint.org to detect latency, packet loss, and errors early, enabling timely response and reducing downtime.
- Implement redundancy, load balancing, and backup strategies such as active-active setups and failover testing to minimize single points of failure.
- Develop disciplined incident response workflows with defined roles, communication templates, and timely updates to reduce confusion during outages.
- Conduct thorough postmortems after incidents to document root causes, assign actions, and continuously improve processes to prevent future network solutions outages checkerpointorg.
Why Network Solutions Outages Happen — Root Causes To Watch For
Hardware fails. Power fails. Software bugs crash services. Misconfiguration blocks traffic. Capacity limits overload routers and switches. Human error disconnects links or applies wrong rules. External events like fiber cuts and DDoS attacks disrupt networks. Lack of visibility hides slow failure modes. Poor change control lets risky updates pass to production. Teams should list these causes and assign owners. They should use clear metrics to detect each cause. Teams that plan for these causes reduce the chance to prevent network solutions outages checkerpointorg from escalating.
Use Checkpoint.org To Monitor, Detect, And Correlate Outages
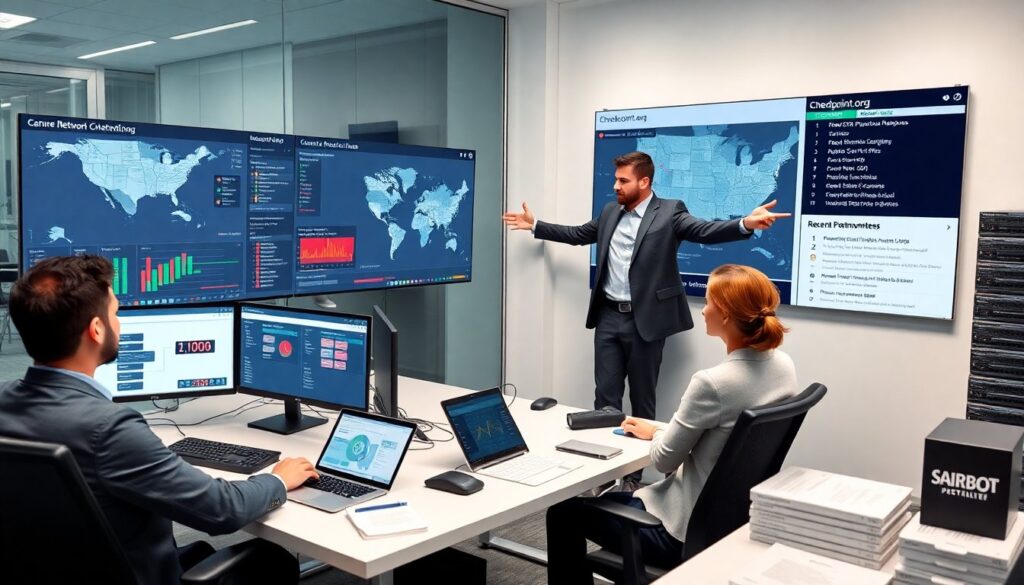
Checkpoint.org collects logs, SNMP, and synthetic checks. The platform ingests telemetry from routers, firewalls, and servers. It normalizes data and shows correlated events. Users can map alerts to services and to network paths. Analysts can filter by device, region, or error type. The platform keeps historical records for trend analysis. Teams use Checkpoint.org to spot slow trends before they trigger outages. This practice helps teams prevent network solutions outages checkerpointorg by turning raw signals into actionable incidents.
Setting Up Alerts And Dashboards On Checkpoint.org
Teams create service-level dashboards that show latency, packet loss, and error rates. They set thresholds for immediate alerts and for early-warning alerts. Alert rules target the right teams and include runbooks. Dashboards show top failing devices and the last recovery action. Analysts use color and simple indicators to reduce misreading. They test alerts weekly and tune thresholds by load patterns. This setup helps teams prevent network solutions outages checkerpointorg by ensuring timely detection and clear assignment of work.
Proactive Infrastructure Practices To Reduce Single Points Of Failure
Teams build redundant links and dual-homed devices. They place critical services across sites. They test failover paths in maintenance windows. They apply version control to device configs and stage changes in labs. Teams automate backups of configurations and validate restores. They size capacity with 30 to 50 percent headroom for peak loads. They monitor spare parts and replace aging hardware on schedule. These steps lower the risk that a single failure will cause an outage. They help teams prevent network solutions outages checkerpointorg by reducing impact windows.
Redundancy, Load Balancing, And Backup Strategies That Work
Use active-active load balancing for web and API tiers. Deploy stateful failover for firewalls where possible. Replicate critical state to a secondary site with low-latency links. Schedule nightly snapshots for system images and weekly full backups for configuration data. Use DNS health checks to steer traffic away from degraded sites. Run periodic restore drills to confirm backups work. These tactics give clear recovery paths. They let teams prevent network solutions outages checkerpointorg by shortening recovery time and reducing data loss risk.
Incident Response, Communication, And Postmortem Workflows
Teams define incident roles and an escalation path. They set clear communication templates for internal teams and for customers. The incident lead opens a war room and assigns tasks. Teams log timeline entries with timestamps and actions. They capture command outputs and configuration snapshots for evidence. They keep stakeholders informed with short, regular status updates. They close incidents only after service verifies stability. This discipline improves recovery and helps teams prevent network solutions outages checkerpointorg by reducing confusion during incidents.
Conducting Postmortems And Continuous Improvement After An Outage
After service restores, the team runs a postmortem within seven days. They document the timeline, root cause, and detection gap. They list specific action items, owners, and due dates. They track action completion and verify fixes in production. They update runbooks, alerts, and training material based on findings. They share a short summary with leadership and affected customers. This loop turns failures into lessons. It helps teams prevent network solutions outages checkerpointorg by closing gaps that caused the outage.